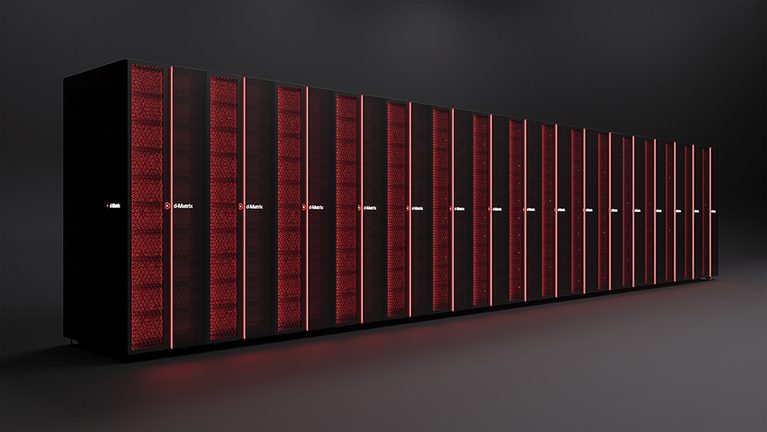
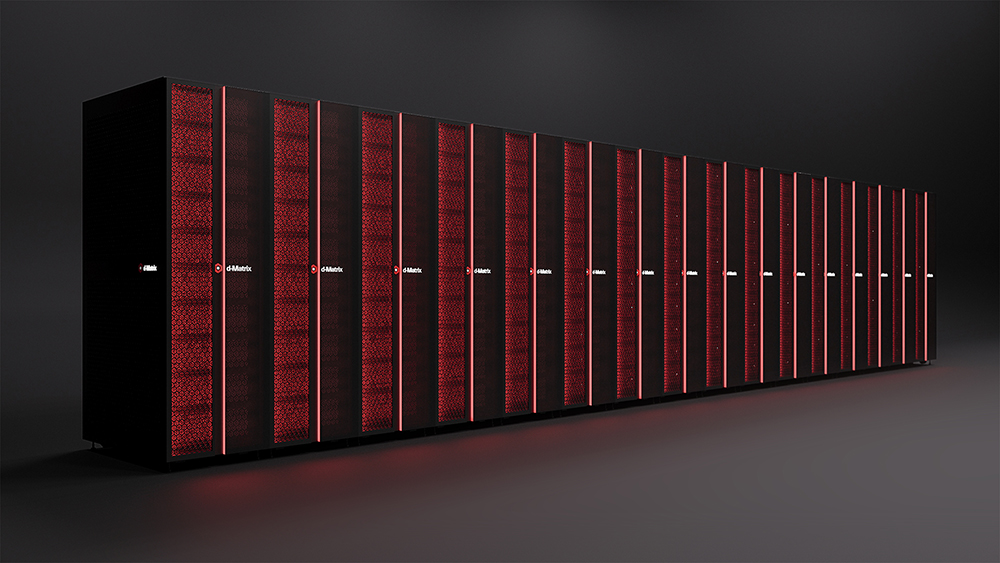
d-Matrix has introduced Squadron, a multi-rack AI inference compute cluster designed to scale to data center deployments and target ultra-low-latency workloads. The company describes Squadron as “megawatt-scale” inference infrastructure aimed at latency-sensitive applications such as coding assistants, personal agents, cybersecurity, and high-frequency trading.
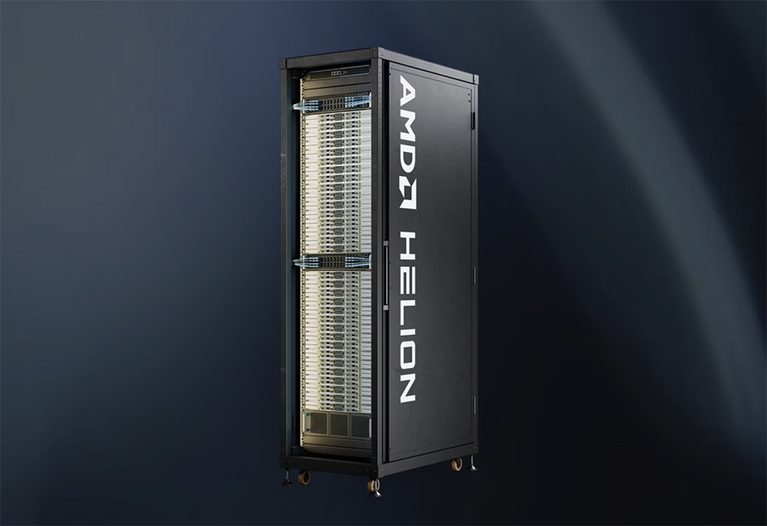
Squadron is built around the d-Matrix Corsair platform and scales from single-server deployments to multi-rack clusters. In its largest stated configuration, a Squadron cluster scales to 16 d-Matrix SquadRacks, which d-Matrix defines as single eight-server racks, for a total of up to 1,024 d-Matrix Corsair XPUs. The cluster interconnect uses d-Matrix JetStream NICs and is deployed and managed with d-Matrix Aviator software.
A practical detail for facilities teams is the cooling assumption: d-Matrix states that Squadron clusters are air-cooled and built on “industry standards,” with the intent that they can be integrated into existing data centers without requiring a shift to liquid cooling or a dedicated facility buildout. That doesn’t eliminate the usual constraints around megawatt-scale deployments, but it does keep the mechanical integration story closer to conventional high-density air-cooled rollouts.
d-Matrix says Squadron was developed in partnership with Arista, Broadcom, and Supermicro. The company also says it has deployed Squadron in its Arizona data center for internal research and development and that Squadron systems are now shipping to “priority customers” for deployment in their own data centers. In addition, d-Matrix says the platform building blocks—Corsair servers and Corsair SquadRacks—are generally available.
On the workload side, d-Matrix says Squadron can run full models exclusively on Corsair XPUs and is also designed for heterogeneous deployments where work is split between GPUs and XPUs using disaggregated compute. The company highlighted an implementation of Attention-FFN Disaggregation (AFD) using its own Squadron system paired with GPU servers, where it reported 845 tokens per second per user. With 64 concurrent users, d-Matrix reported total throughput of 20,415 tokens per second for that heterogeneous AFD setup.
“With Squadron shipping, and our Corsair servers and SquadRacks now generally available, the wait is over,” said Sid Sheth, founder and CEO of d-Matrix.
Source: d-Matrix