Kopin and Fabric.AI published a white paper analyzing an optical interconnect approach, Neural I/o, that aims to move AI clusters beyond short-reach copper connections and expand how tightly GPUs can be connected across a data hall. The paper models system-level impacts, including higher “useful training throughput” per GPU, by reducing losses tied to communication, synchronization, and reliability overhead.
The white paper, titled “The Data Center in a SerDes-Free World”, is authored by Kopin CEO Michael Murray, Kopin Senior VP of Engineering Dr. John Callahan, and Fabric.AI Senior Strategic Advisor James Altucher. Rather than focusing only on link-level improvements, it evaluates how an optical fabric could change AI system architecture when connectivity can extend beyond roughly 1 m to “tens of meters.”
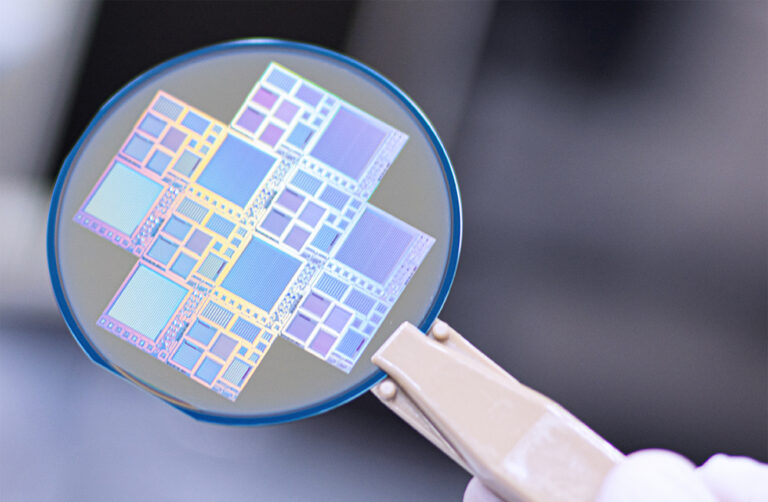
Neural I/o replaces a small number of high-speed serialized electrical links with massively parallel MicroLED-based optical channels. In the model, the longer-reach, high-bandwidth connections expand a tightly coupled compute domain from roughly 72 GPUs today to row-scale configurations spanning hundreds or more than 1,000 GPUs. The authors argue that this shift could also change physical layout assumptions, reducing the rack’s role as the primary building block and enabling switching infrastructure to be separated from compute racks.
Modeled system-level figures
For a 10,000-GPU system, the paper models 1.3 to 1.6 times greater useful training throughput per GPU, which it equates to about 23% to 38% less training time for the same workload. The modeled improvement comes from reducing communication-, synchronization-, and reliability-related losses rather than increasing GPU compute performance.
The modeled Neural I/o architecture includes 3.2 Tb/s of payload bandwidth and uses additional optical channels for redundancy, synchronization, timing, telemetry, and control. The paper argues that the extra channel capacity could help coordinate GPUs, absorb individual channel failures, and monitor interconnect health without contending with primary AI workload traffic.
Why data center engineers should care
If row-scale GPU domains become practical, it changes where operators may want to place switching, how they cable and service interconnects, and how they plan cooling and containment around compute versus network-heavy zones. But the numbers here are modeled, not measured, and real-world outcomes will hinge on implementation details like failure behavior, operational complexity, and how the optical fabric behaves at scale.
Kopin and Fabric.AI have begun initial transmission-link testing of Neural I/o. Kopin is targeting a public technology demonstration in January 2027 and “first-generation production silicon” in 2028, according to the companies. Michael Murray said, “When the physical limitations of today’s interconnect no longer dictate that system’s architecture, our analysis shows the potential for better utilization of existing compute and much greater freedom in how future AI infrastructure is designed.”
Source: Kopin